Sophia is an AI-powered knowledge base assistant built on top of Ulabase. It turns static documentation (PDFs, Markdown files, HTML pages) into a conversational agent that answers questions and cites the source documents it draws from. It uses RAG (Retrieval-Augmented Generation) combined with large language models (Claude by Anthropic, Amazon Bedrock) to find and synthesize relevant content from your knowledge base.
In April the team worked on three things: how the agent decides when to search, operational costs, and recovery when the infrastructure has problems.
Where to Try Sophia
SoftInstigate operates two public instances:
- RESTHeart documentation at bysophia.ai/restheart
- Ulabase docs at bysophia.ai/cloud
Both instances are also accessible as MCP servers from Claude Code, Claude Desktop, and any other MCP-compatible AI client.
Smarter, Cheaper Retrieval with the Search Preamble
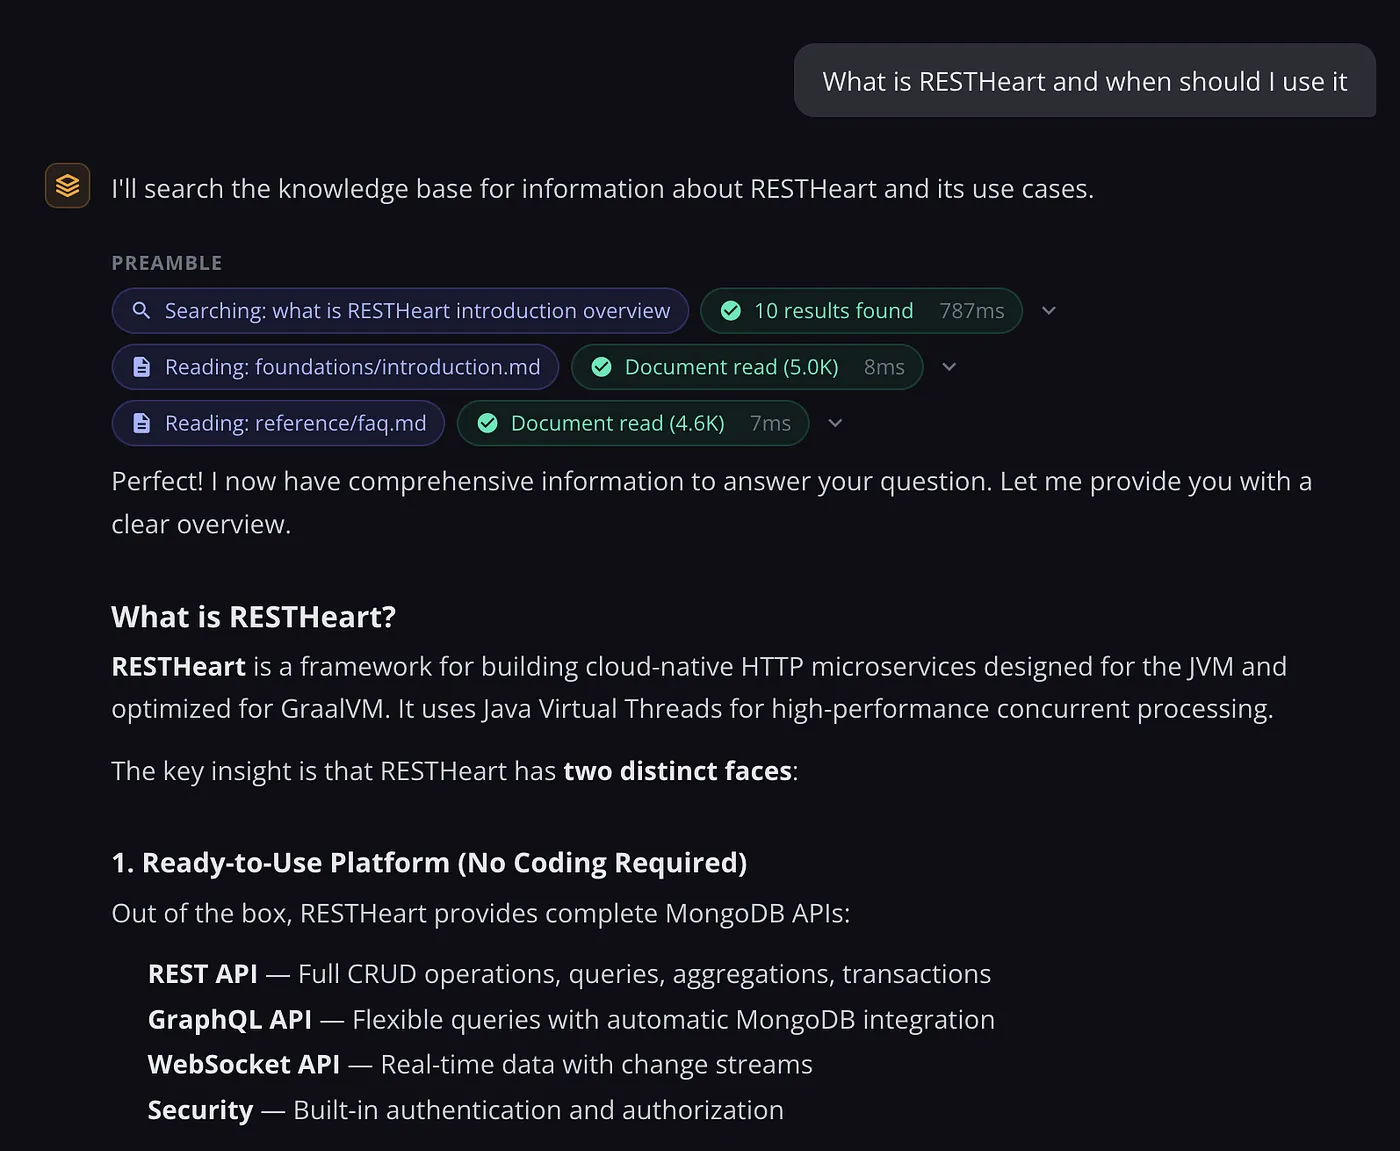
The main change this month is a search-and-fetch preamble that runs searches before the agentic loop begins. On typical queries it reduces input tokens by approximately 76%.
The mechanism includes a lightweight planning call that determines whether a knowledge base search is necessary. The model evaluates the full conversation and decides if retrieval makes sense or if the answer already exists in context. When retrieval is needed, the preamble fetches the relevant documents before the main loop starts, so the agent reasons from prepared context and does not search in the middle of a response.
Agent-Managed Memory as an Alternative to History
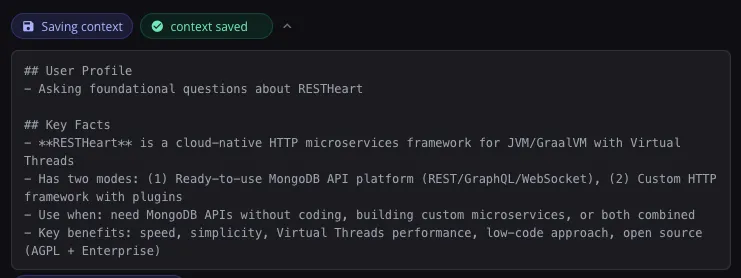
The agent now manages its own memory through dedicated tools: it can save, append to, or patch context documents stored in MongoDB. Entire conversation histories are no longer injected into each prompt.
This keeps long conversations affordable. The context size reflects what the agent considers important, so a 20-turn discussion does not get more expensive at every turn.
Prompt Caching
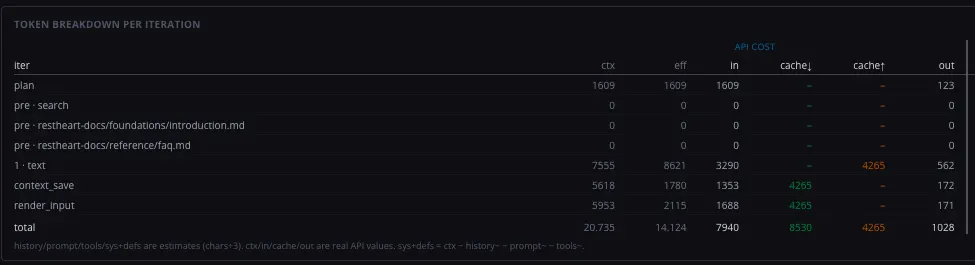
The system now caches the system prompt, tool definitions, and history prefix as a contiguous block. Cached content costs roughly one-tenth of normal pricing on subsequent iterations within the same session.
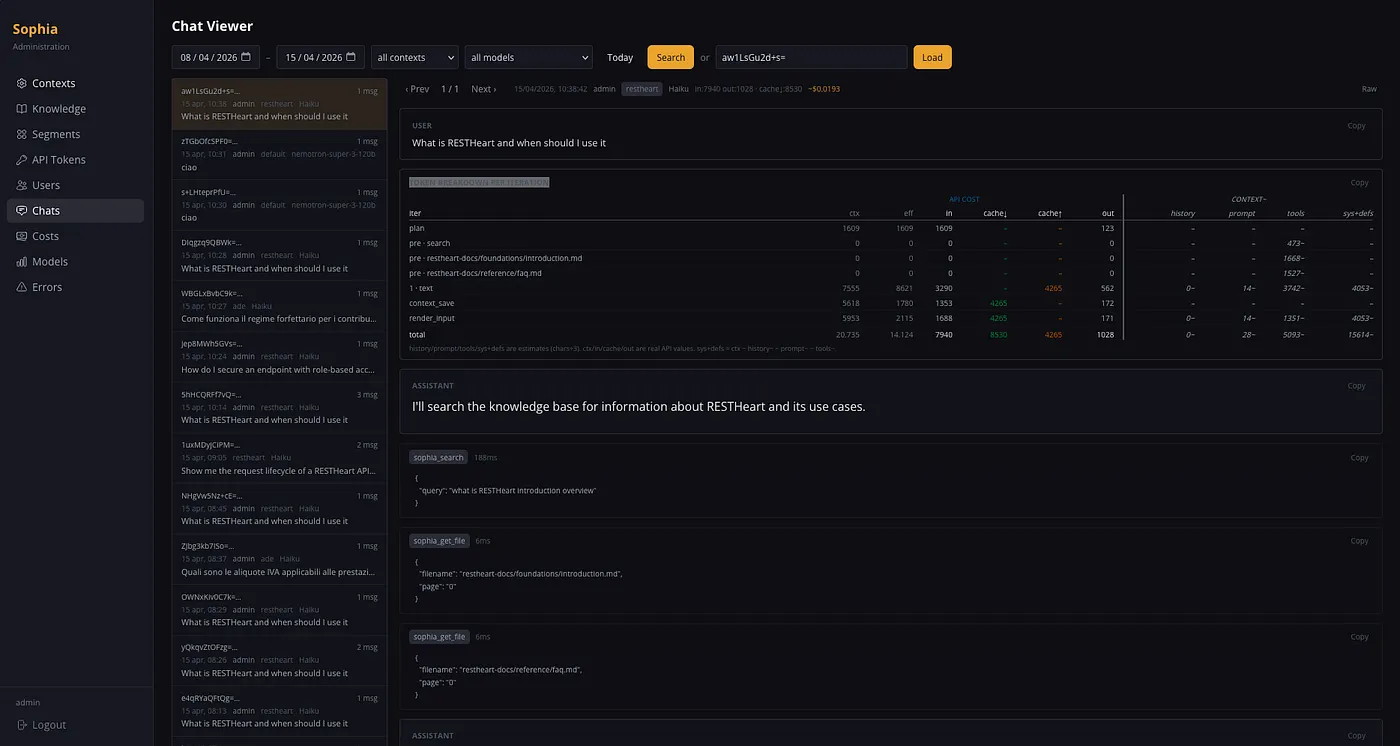
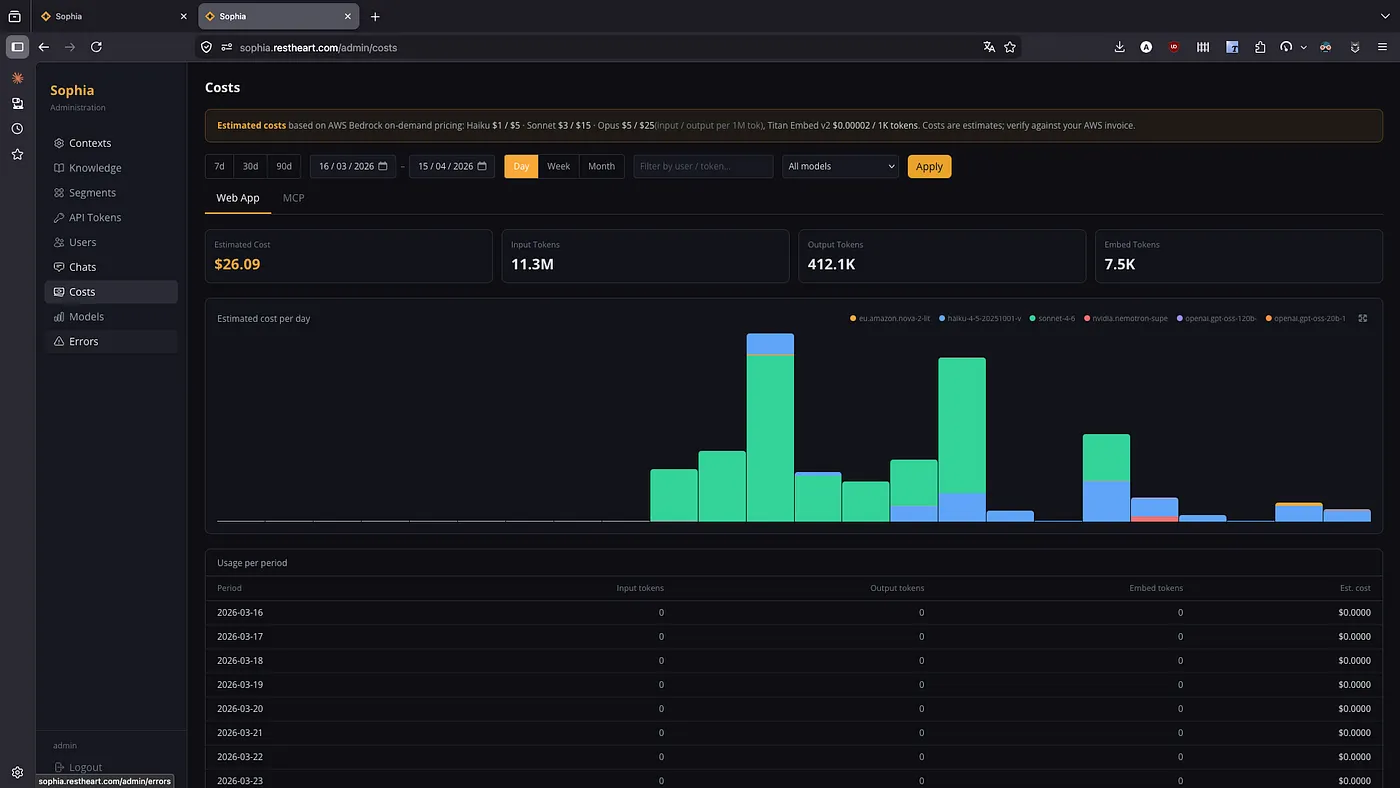
The admin panel displays per-iteration token tracking (input, output, cache reads, and cache writes) for each interaction, so administrators see what is being cached and at what cost.
Automatic Failover When Bedrock Has Problems
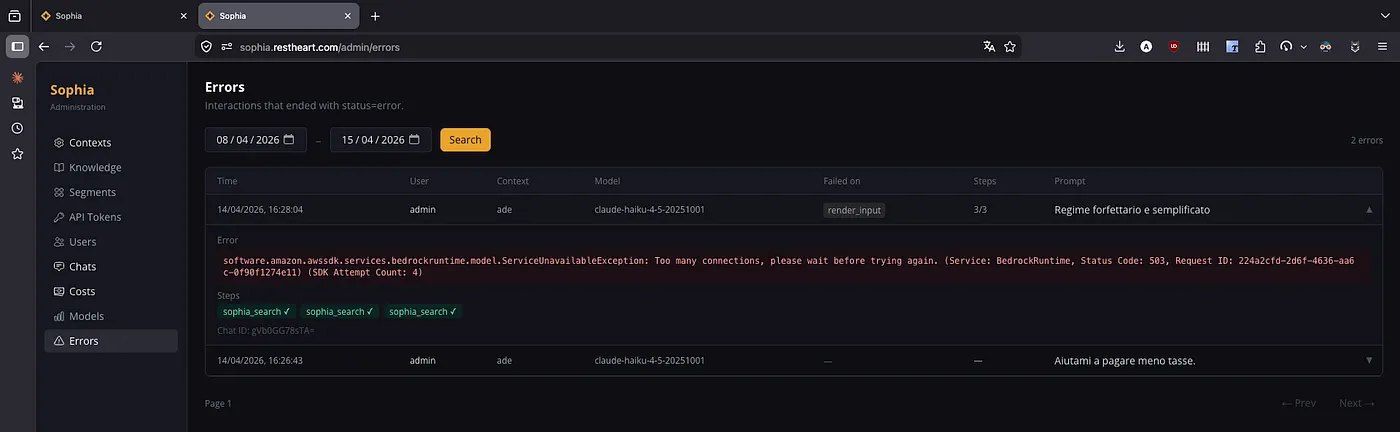
AWS Bedrock transient errors (503 and 500 responses) now trigger automatic retries with fallback models. The fallback is per-request only, with no persistent state change or circuit breaker: normal behavior resumes as soon as Bedrock recovers.
Enhanced Admin Panel
Three new sections in the administration panel:
- Chat sessions viewer: searchable, filterable interaction table with cost breakdowns and token economics per session and per interaction
- Error list: shows all failed interactions with error messages and full context, to diagnose model or retrieval failures
- Models admin page: lists configured Bedrock models with pricing, throughput limits, quotas, and tool-use capability scores
Artifact Share Links
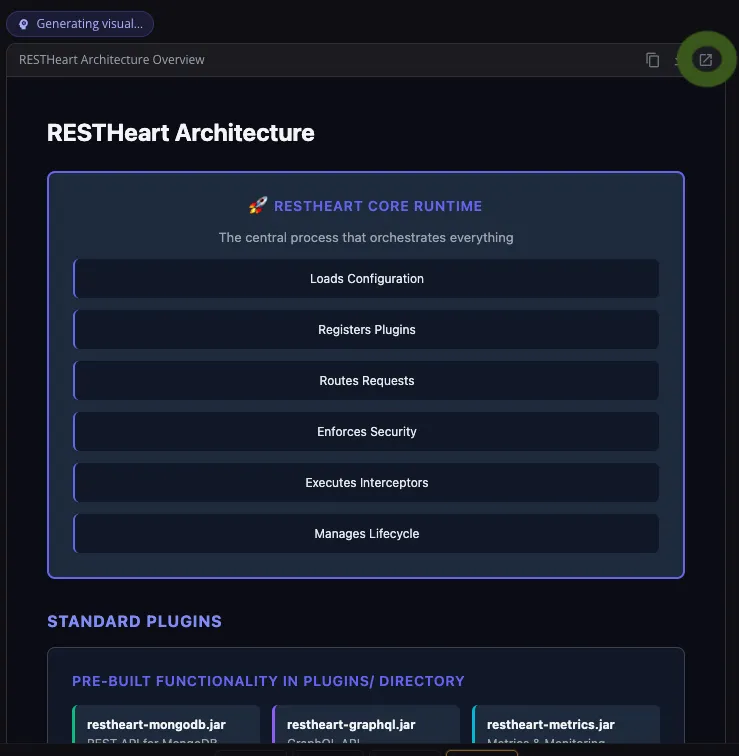
render_output artifacts can now be shared via read-only links without requiring recipients to authenticate. Access control is still enforced at the database level: unauthenticated sharing only works for artifacts in public contexts.
Streaming Reliability
A watchdog now detects stalled connections and triggers automatic recovery. The streaming timeout was also extended to 30 seconds, so longer responses no longer hit false timeouts.
Build your app on Ulabase
Your backend is ready in minutes, and you spend your time on your app. The Free plan needs no credit card.